Data Analysis: From Spreadsheets to Python
You already think in rows, columns, and pivot tables. Here is why those same instincts make pandas the natural next step, and when it is worth the switch.
TL;DR
If you think in rows, columns and pivot tables, pandas is a natural next step: a DataFrame is a sheet you can type, and groupby is the pivot table you already love. Python pays off for repetitive reports, big files and traceable analysis, while spreadsheets still win for small, quick, visual work.
On this page
If you spend your days in spreadsheets, you have probably had the thought more than once: there has to be a faster way. Maybe you rebuild the same monthly report by hand, dragging the same formulas down the same columns. Maybe a file arrives that is simply too big to open without your machine grinding to a halt. Maybe a number in a report looks wrong and you spend an hour tracing through hidden formulas and merged cells trying to figure out how it was calculated. These are not failures of skill. They are the natural limits of a tool built for small, visual, hands-on work.
Python, and specifically the pandas library, is the tool people reach for when they hit those limits. The good news, and the reason this transition is more comfortable than it sounds, is that pandas was designed around the same mental model you already use. You are not starting over. You are relabeling skills you already have.
A sheet you can type
The heart of pandas is an object called a DataFrame. The simplest way to understand it is this: a DataFrame is a sheet that lives inside your code. It has named columns, like a header row. It has numbered rows, like the numbers down the left of your spreadsheet. Each column has a type, numbers, text, or dates, just as a spreadsheet column does. A single column has its own name, a Series, and that is where most of your calculations happen.
Watch how closely the two worlds line up. In a spreadsheet you might click an empty cell and type equals AVERAGE of B2 through B500. In pandas you write df[“revenue”].mean(). The spreadsheet points at a range of cells by their coordinates. The pandas line points at a column by its name. That single shift, from cell coordinates to named data, is most of what moving to code actually feels like. Once you stop thinking in B2:B500 and start thinking in “the revenue column,” the rest follows quickly.
Adding a calculated column shows the same pattern. In a spreadsheet you type a formula in the first cell and drag it down hundreds of rows. In pandas you write the formula once, for example df[“total”] = df[“price”] * df[“units”], and it applies to every row at the same moment. There is nothing to drag and nothing to accidentally stop halfway. pandas treats a whole column as one thing, which is both faster and far less error-prone.
The pivot table you already love
The feature spreadsheet users are most attached to is the pivot table, and it has a direct pandas equivalent called groupby. The idea behind both is identical: split the data into groups, then compute a summary for each group. When you drag “region” into the rows of a pivot table and “revenue” into the values set to SUM, you are grouping by region and summing revenue. In pandas that exact operation reads df.groupby(“region”)[“revenue”].sum(). Group by region, take the revenue column, add it up within each group. Want averages instead of totals, swap sum for mean. Want to break it down by region and product together, pass both names. The pivot table’s power carries over completely; only the way you express it changes.
So why switch at all?
If pandas just mirrors the spreadsheet, what do you gain? The answer is that your work stops being a pile of clicks and becomes a written recipe. Every step, loading the file, cleaning a column, filtering rows, grouping, charting, is a line of plain text that you can read, save, and run again. That difference quietly solves the three pains we started with.
Repetition disappears. The script that builds this month’s report builds next month’s report when you point it at the new file. There is no re-dragging and no chance of dropping the wrong field into the pivot.
Size stops mattering. The same few lines that summarize a thousand rows summarize a million with no extra effort, well past the point where a spreadsheet would stall or refuse to open.
And trust returns. Because every transformation is written out in order, anyone, including the version of you six months from now, can see precisely how the final number was produced and reproduce it exactly. There are no hidden formulas, only steps you can read.
When to stay put
None of this means spreadsheets are obsolete. For a quick one-off calculation, a small budget, or a chart you need in the next five minutes for a meeting, the spreadsheet is still the fastest, friendliest tool on your desk. It is also the easiest thing to hand to a colleague who does not write code. A healthy workflow often uses both: explore and sketch ideas in a spreadsheet, then translate the parts you repeat into a Python script that runs reliably forever. pandas even reads and writes spreadsheet files, so the two tools pass data back and forth without friction.
Where to begin
You do not need to master Python to get value on day one. Install the Anaconda distribution, which bundles everything, open a Jupyter notebook, and try four lines: read a CSV with pd.read_csv, look at it with head, summarize it with groupby, and draw a chart with plot. That tiny loop, load, inspect, summarize, visualize, is the whole job in miniature, and it will feel surprisingly familiar.
The move from spreadsheets to Python is not a leap into the unknown. It is a short step onto firmer ground, carrying the instincts you already trust. A tab becomes a DataFrame, a column becomes a Series, a pivot table becomes a groupby, and your weekly grind becomes a recipe you run once and reuse forever.
Key takeaways 5
- Spreadsheet skills transfer directly to pandas.
- A DataFrame is a sheet you control with code.
- groupby and pivot_table replace manual pivot tables.
- Switch when reports repeat, files grow large or you need reproducibility.
- Spreadsheets remain great for small, one-off, visual work.
Watch & learn

Frequently asked questions
Why move from Excel to Python for data analysis?
Python handles larger datasets, automates repetitive reports, makes every step traceable and reproducible, and connects easily to databases, APIs and visualization tools.
What is pandas?
pandas is a Python library for working with tabular data. Its DataFrame works like a spreadsheet with rows and columns, but you filter, transform and summarize it with code.
How do I start learning pandas as an Excel user?
Recreate a report you already build in Excel: load the file with read_csv or read_excel, then filter, add columns and summarize with groupby to see the equivalent operations.
Go deeper with the free masterclass
Workshop, PDF handbook and curated resources for “Data Analysis: From Spreadsheets to Python”.
Related articles
Data Cleaning & Wrangling with pandas
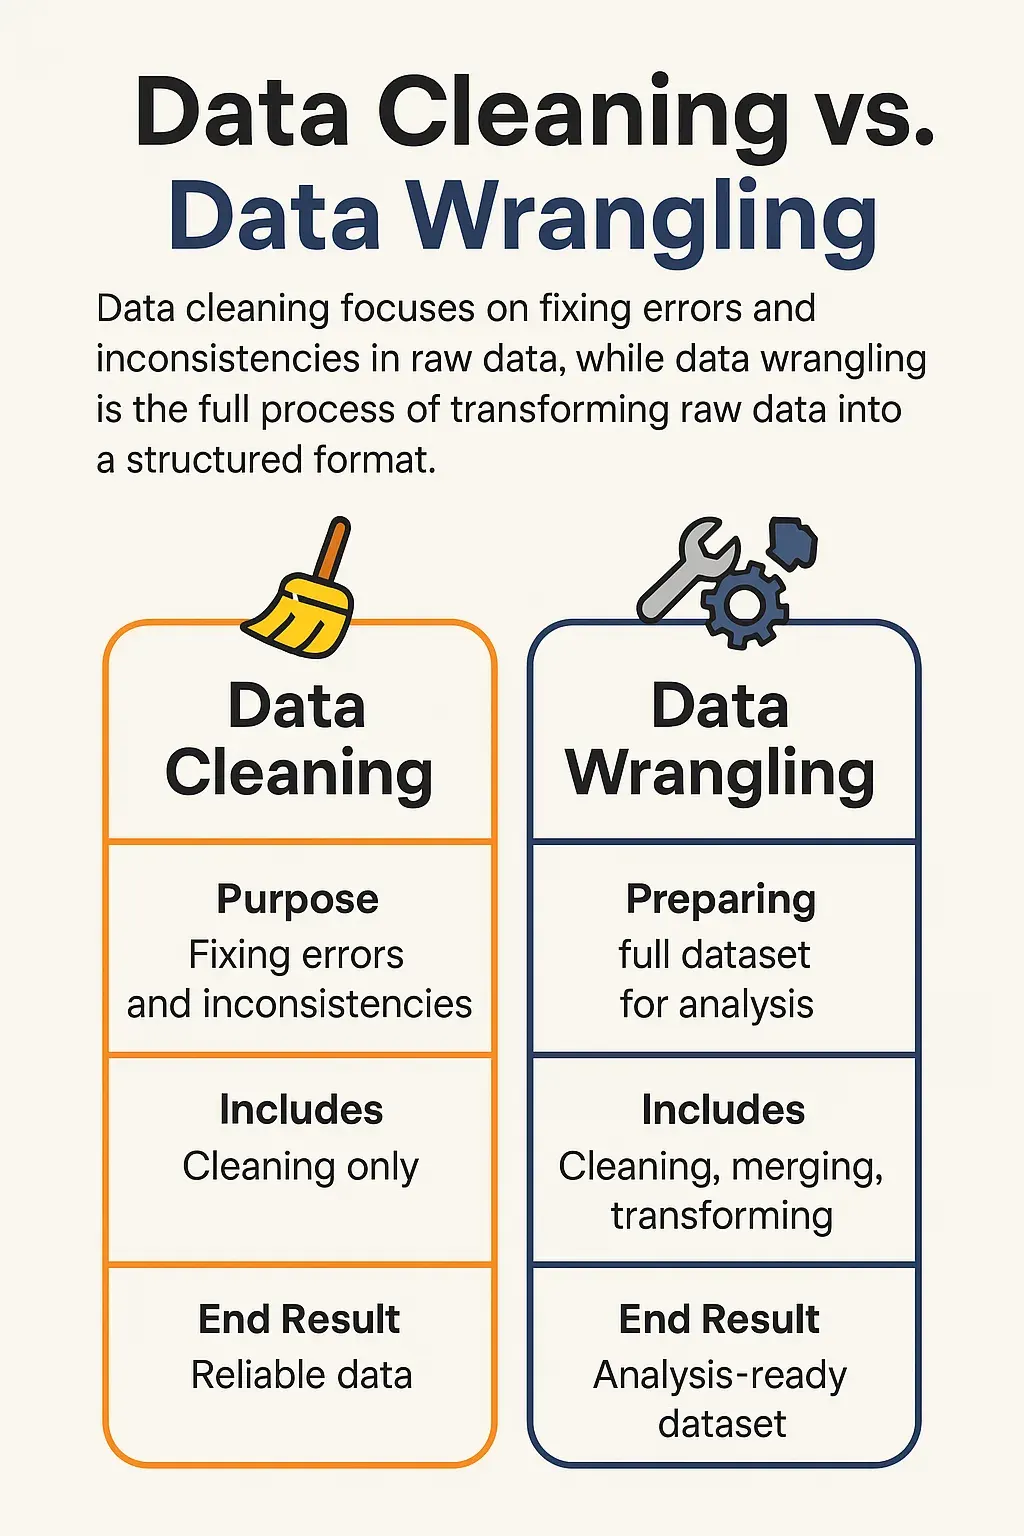
Analysts love to talk about models and dashboards, but the real job is mostly cleaning. Here is why that unglamorous work deserves more respect - and a sharper method.
Machine Learning for Analysts
You do not need a PhD to build a useful model. You need to frame the problem, respect the test set, and know when to stop.
Practical Big Data Analytics
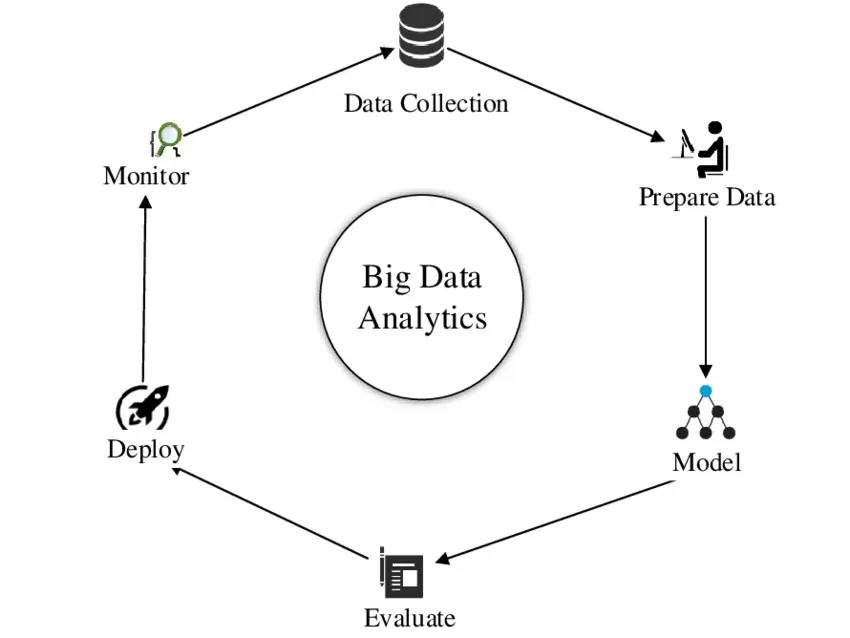
Everyone wants to say they work with big data. The freeing truth is that almost nobody does - and that means your laptop is more powerful than you think.
Comments
No comments yet. Start the conversation.